从 FASTA 或候选肽段预测碎片强度与保留时间,减少实验建库需求。搜索空间、模型适配和实测校准仍影响 FDR、速度与结果深度。
directDIA
项目内两步式工作流
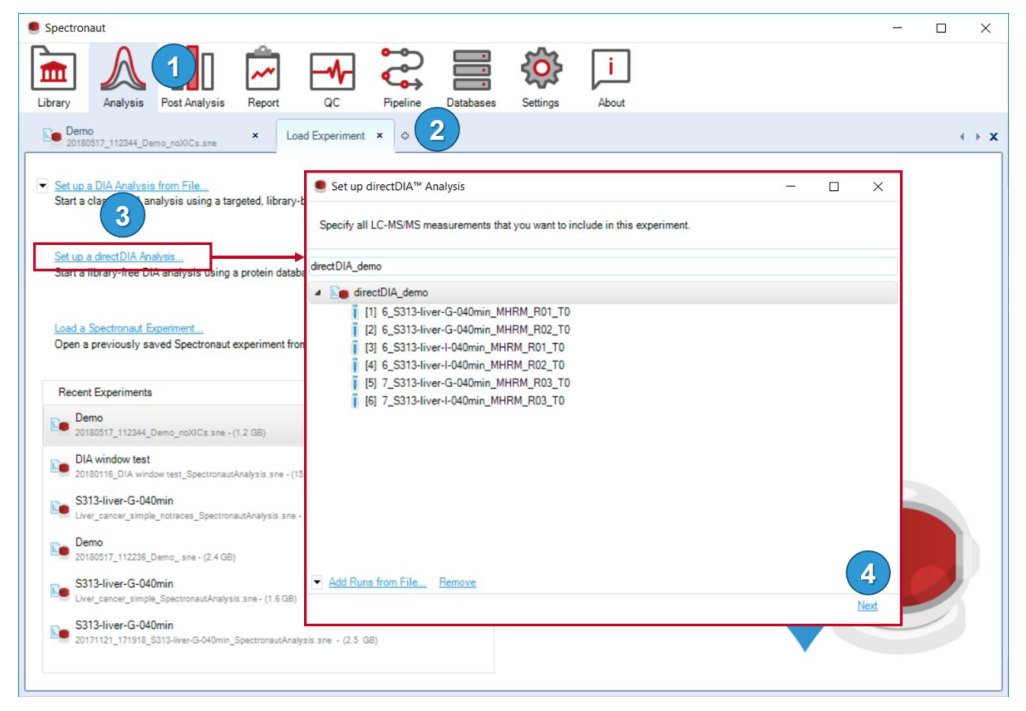
以 DIA 原始数据和 FASTA 先执行 spectrum-centric 搜索,生成项目特异谱库,再对同一批 DIA 运行进行 peptide-centric 靶向提取和定量。它绕过预先建立的外部实验库,但不绕过数据库、搜索空间和 FDR。
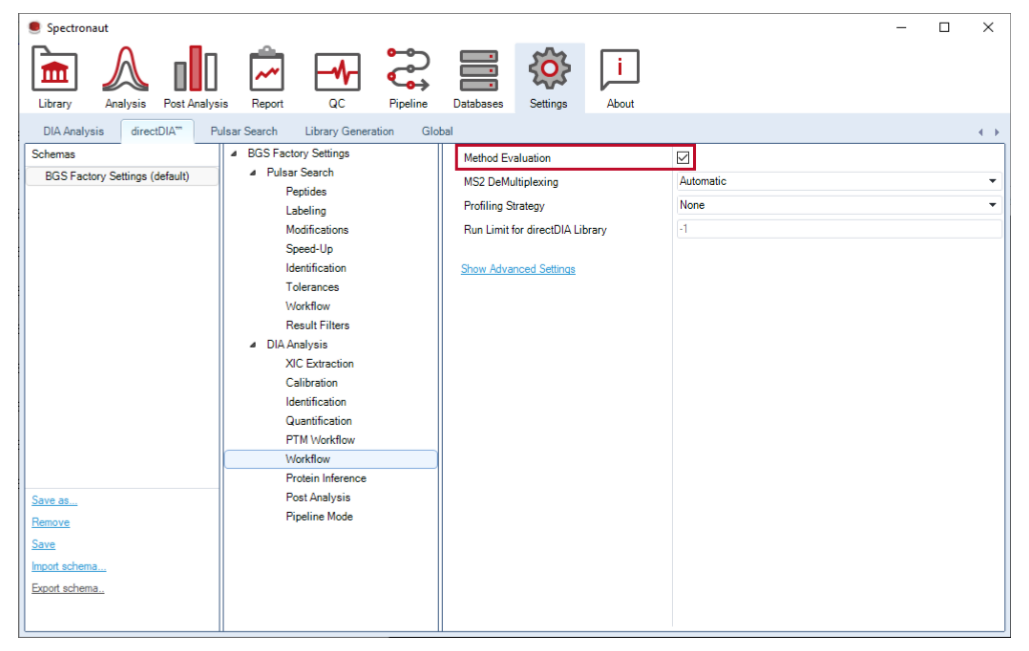
directDIA 输入仍需明确。运行文件、FASTA、注释和设置共同定义项目内搜索与建库空间。图示来源:本门户 Spectronaut 正式手册资料。方法评估与正式定量要区分。采集方法比较用于选择 DIA 方法,不等同于带生物学分组的正式定量实验。图示来源:本门户 Spectronaut 正式手册资料。
实验设计
把 benchmark 做成项目质量控制,而不是一次性演示
01
定义真值和方向
在采集前固定参照组、比较组、理论比例、log2FC 方向和可进入准确性计算的唯一归属对象。
02
设置重复与批次平衡
生物学重复、技术 QC 和样品随机化用于区分方法波动、批次漂移与真实生物差异。
03
保留层级
precursor/肽段层用于定位干扰和缺失来源,蛋白层用于评价最终报告;两层结论不能互相替代。
04
完整数据统计
大表可以抽样绘图或分页展示,但总数、分位数、CV、完整性、阈值占比和打分必须使用完整结果。
05
报告可靠区间
按丰度、物种和批次说明在哪些区间内 CV、完整性和误差可接受,并列出需要复核或不能外推的对象。
06
保存参数与来源
报告应记录软件版本、搜索策略、FDR、定量层级、归一化、缺失处理、分组和阈值,以支持复算与审计。
常见结论
可以支持
不能自动支持
重复 CV 较低
当前组内测量具有较好精密度
理论比值恢复准确、没有系统偏差
Pearson r 较高
样品整体丰度排序相似
低丰度蛋白可靠、每个 fold change 都准确
蛋白鉴定数较高
当前搜索和阈值下覆盖较深
跨样品完整、干扰较低、物种特异
HYE 误差较低
受控混合样品的比值恢复良好
所有真实生物样品、基质和动态范围都同样可靠
原始文献
经典方法与 benchmark 研究
以下论文分别对应 DIA 采集、peptide-centric 提取、LFQ 汇总、软件工作流、跨运行对齐、混合物种 benchmark、预测谱库、神经网络分析和大队列重复性。
2004 · DIA 前身Venable JD, et al. Automated approach for quantitative analysis of complex peptide mixtures from tandem mass spectra.Nature Methods · DOI
2012 · SWATHGillet LC, et al. Targeted data extraction of the MS/MS spectra generated by data-independent acquisition.Molecular & Cellular Proteomics · DOI
2014 · OpenSWATHRöst HL, et al. OpenSWATH enables automated, targeted analysis of data-independent acquisition MS data.Nature Biotechnology · DOI
2014 · MaxLFQCox J, et al. Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction.Molecular & Cellular Proteomics · DOI
2015 · SpectronautBruderer R, et al. Extending the limits of quantitative proteome profiling with data-independent acquisition.Molecular & Cellular Proteomics · DOI
2016 · LFQbenchNavarro P, et al. A multicenter study benchmarks software tools for label-free proteome quantification.Nature Biotechnology · DOI
2016 · TRICRöst HL, et al. TRIC: an automated alignment strategy for reproducible protein quantification in targeted proteomics.Nature Methods · DOI
2017 · 多实验室Collins BC, et al. Multi-laboratory assessment of reproducibility, qualitative and quantitative performance of SWATH-MS.Nature Communications · DOI
2019 · PrositGessulat S, et al. Prosit: proteome-wide prediction of peptide tandem mass spectra by deep learning.Nature Methods · DOI
2020 · DIA-NNDemichev V, et al. DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput.Nature Methods · DOI
2020 · 大规模重复性Bruderer R, et al. Strategies to enable large-scale proteomics for reproducible research.Nature Communications · DOI
2023 · directLFQAmmar C, et al. Accurate label-free quantification by directLFQ to compare unlimited numbers of proteomes.Molecular & Cellular Proteomics · DOI
技术摘要与资料依据
DIA 按预设质荷比窗口采集碎片信号。采集窗口、循环时间、色谱峰宽与后续检索策略共同影响可解析的证据;谱库检索和 library-free 分析均需要明确鉴定层级、FDR 控制和定量质量标准。